 1:12:31A 100-Year-Old Solution to AI Work Slop
YouTubeCal Newport
Current feed – 8 topics from 31 creatorsPersonalize your feed
1:12:31A 100-Year-Old Solution to AI Work Slop 2:04:12Russian Honeypot: I Was Trained To Control A Man's Mind With Sex! | John Kiriakou & Aliia Roza
 2:18:17416 ‒ The science of mitochondria: their role in health, aging, disease, and much more
A group of physicists has figured out why our universe exists and has not fallen apart long ago t.co/pOhZHxCCHS
Or if it's easier to understand this using the old paradigm, users are the ultimate gatekeepers. Get them and investors will follow. And if not, not. You can fool investors temporarily, but it's not worth doing; if users don't like the product, you're doomed.
The most consistent mistake I see young would-be founders make is to care too much about investors' opinions and not enough about users' opinions. They've been trained their wholes lives to seek out and please the gatekeepers. But this is where gatekeepers stop mattering.
 1:27:16Meta’s Muse: How we launched the most successful consumer product this year | Mona Sarantakos
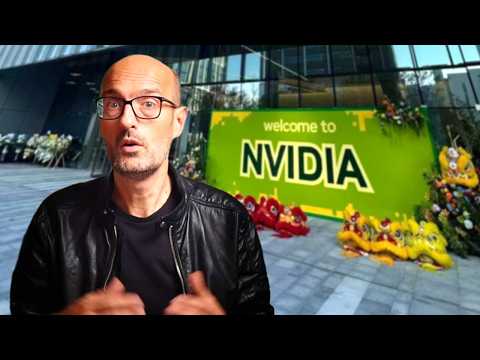 37:49The Risk Factors Nvidia Forgot to Mention
Aside Browser is a huge unlock for every AI agent t.co/lo8Tgqnu9J
On December 9th of the year the EU Product Liability Directive (PLD) will go into effect. For the first time software will have same product liability as physical products. With the recent plane stoppage caused by software & the reckless hacking by leading LLM companies, the US should do the same thing. The creators of the software need to recognize the financial impact that is possible. Which is huge.
 1:00:06The Rise Of AI Coworkers
This is not insane at all. 1/ all D&O programs will have a cap. At NVIDIA's size and with their cash position, its easier to self-insure. 2/ The IRR required by the insurance company would be above their cost of capital, so they would be giving away money. 3/ Large D&O programs attract litigants. You may not know this, but you have to disclose your D&O coverage early in a shareholder lawsuit - which is ridiculous. It would actually make sense to self-insure.
 VeritasiumYouTube
 34:32
 Andrew HubermanYouTube
 2:02:07
 StudioBinderYouTube
 10:53
 Cal NewportYouTube
 1:05:42
 The Diary Of A CEOYouTube
 1:52:58
 Peter Attia MDYouTube
 17:56
 Andrej KarpathyX
Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel. - Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all. - Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract. - Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code. - And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while. The funnel is driven by a combination of factors: 1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel. 2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel. 3. Access. Free-tier, paid-tier, internal. So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.
 Lenny's PodcastYouTube
 1:02:12
 Ali AbdaalYouTube
 28:39
 Patrick BoyleYouTube
 31:45
 Y CombinatorYouTube
 43:23
 Kurzgesagt – In a NutshellYouTube
 17:31Andrew HubermanYouTube
 30:46Cal NewportYouTube
 1:17:50The Diary Of A CEOYouTube
 2:03:32
 FireshipYouTube
 6:10Ali AbdaalYouTube
 20:53FireshipYouTube
 5:46Kurzgesagt – In a NutshellYouTube
 21:44Andrew HubermanYouTube
 2:15:37StudioBinderYouTube
 17:01Cal NewportYouTube
 1:06:45The Diary Of A CEOYouTube
 1:28:12Peter Attia MDYouTube
 2:01:49
 Brian CoxX
Me explaining local gauge invariance, which is probably one of the more ambitious bits of the Arena shows to be honest :-) t.co/vVCWZaOzOy
Lenny's PodcastYouTube 37:23Patrick BoyleYouTube
 33:35Y CombinatorYouTube
 1:20:35Andrej KarpathyX
Cool eval. Simply ask an LLM “Land or Water?” and give it a latitude and longitude coordinate as text. Ask 16,200 times, plot as image. The models know. From compressing the internet. t.co/jTTAhBsMfu
Andrej KarpathyXWe'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks: Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better: Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better: Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better: Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work! In summary: - As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding. - Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.


